Uni-LaDiR: Latent Diffusion Unifies Multimodal Reasoning
TL;DRQuick summary
- Problem: Multimodal reasoning fragments a shared context across modality-specific intermediate representations. Moving to the next thought also requires bridging those interfaces, making cross-modal relationships harder to carry forward.
- Our solution: Uni-LaDiR maps heterogeneous teacher steps into a shared latent workspace, trained to preserve information useful for later reasoning and the final answer or action.
- Why diffusion: A useful next thought need not be unique. Conditional latent diffusion learns multiple possible continuations, generating one block at a time without decoding intermediate modalities.
- Key results: +18.9% relative mean accuracy on eight vision benchmarks versus the matched base model; 87% RLBench success versus LaST₀’s 82%. With teachers and budgets fixed, sharing improves visual reasoning by 7.4% relative and robot control by 3.4% relative.
Consider the scene in Figure 1: a red mug beside a blue book, with a robot ready to act. We can ask two questions about it: “What is beside the blue book?” and “How can the robot pick up the red mug?” The scene is the same, but the information needed to answer changes.
The first question requires identifying the object and its relation to the book. The second also requires relating the mug’s geometry to the gripper’s pose and state. Recognizing the mug does not establish that the fingers can secure it; knowing that the gripper is closed does not establish that it holds the mug. The decision lives in the relationships between observations.
Uni-LaDiR [1] grew out of both practical failures and a modeling intuition: these modalities describe a common, evolving situation. We wanted the model’s intermediate reasoning to carry that situation forward without having to express each new thought in a particular medium. Figure 1 illustrates the design: observations keep their specialized encoders, while intermediate reasoning uses a common interface.
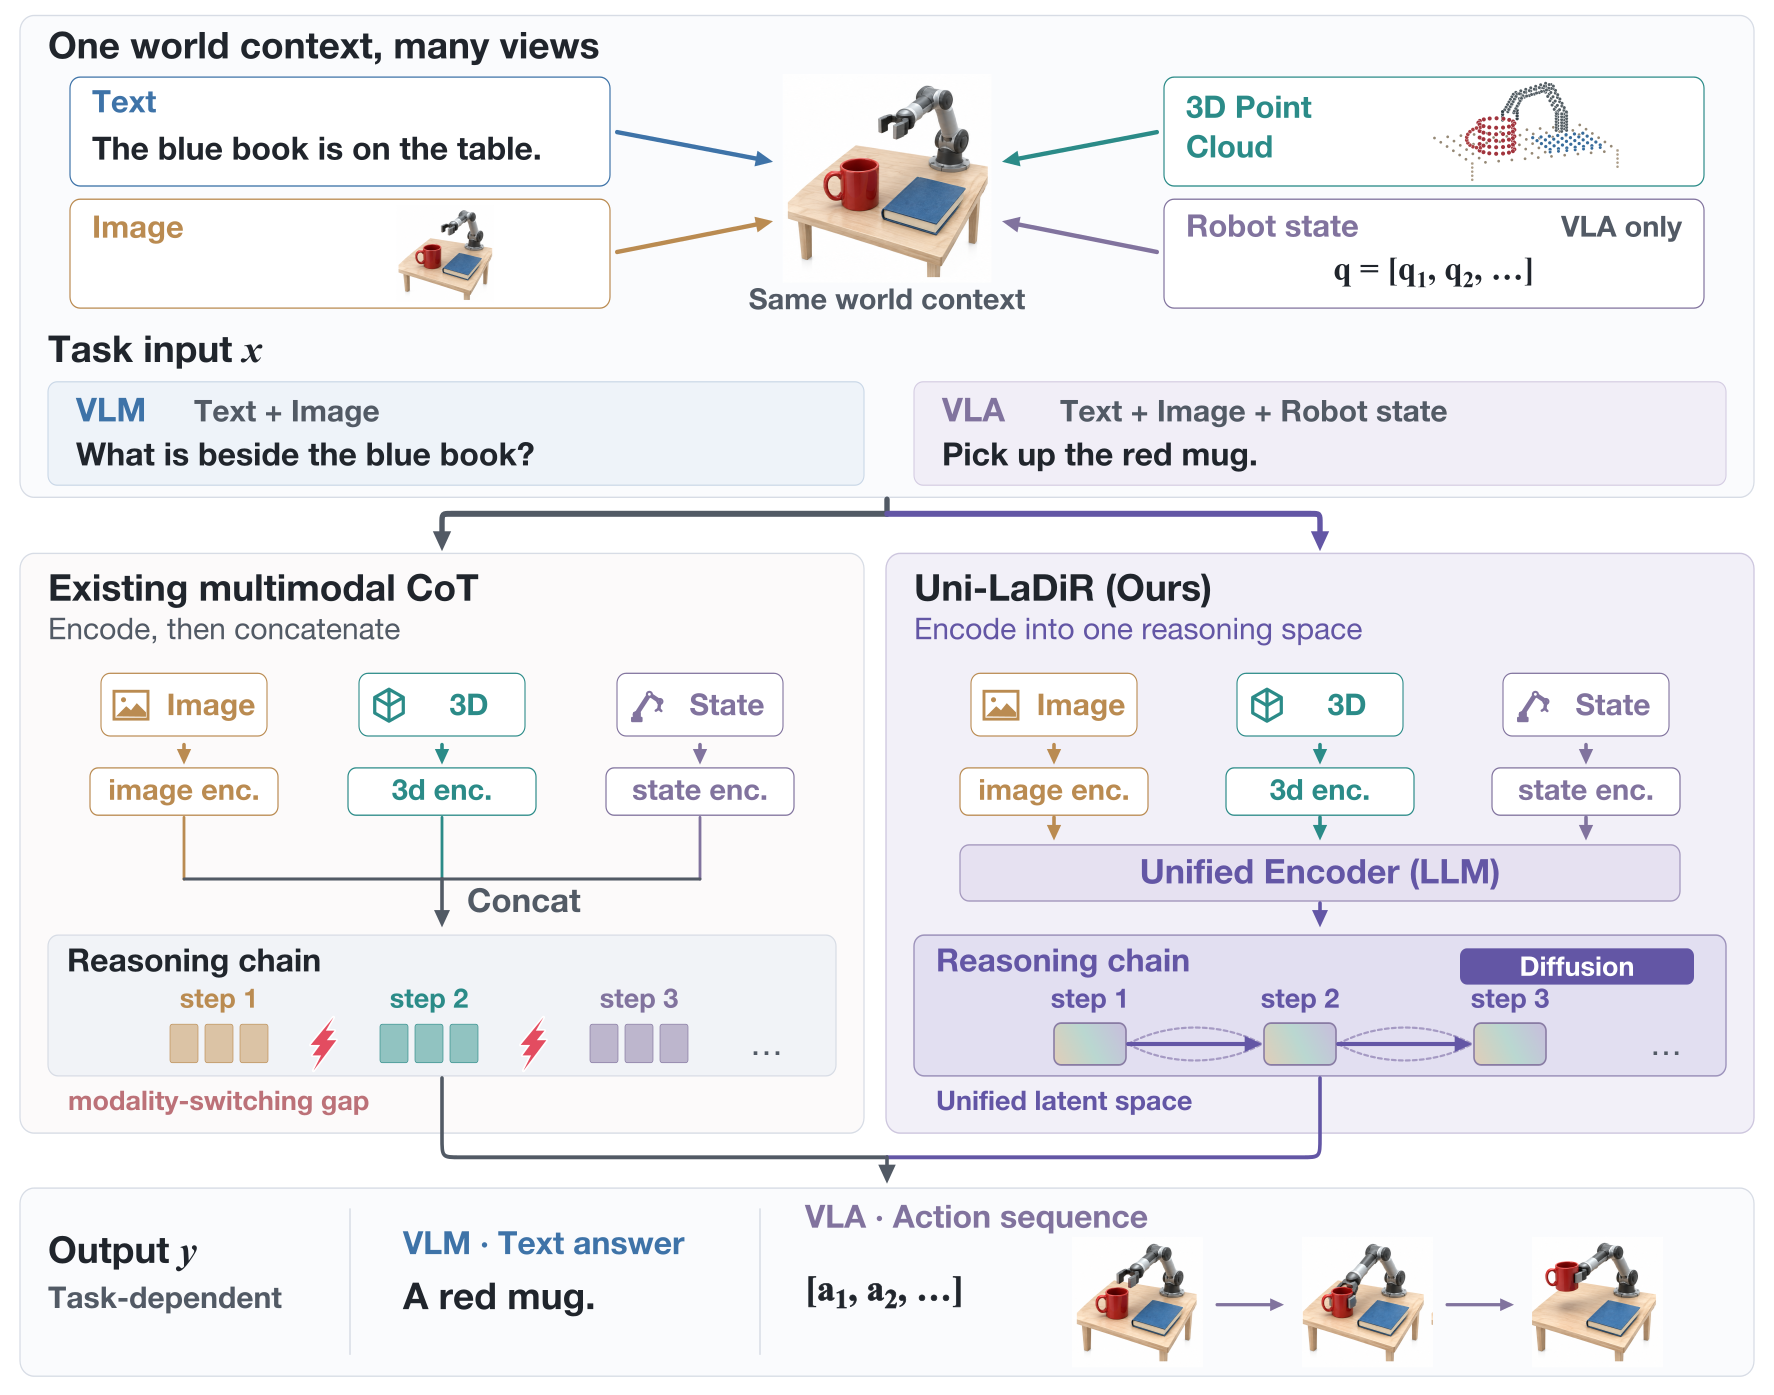
Where information becomes fragmented
A natural approach is to give each modality its own representation, then let a shared model reason over their sequence. This preserves useful specialization: image features need not look like language tokens, and robot coordinates retain their structure. Attention can already connect these representations. Separate encoders are not inherently a problem.
The harder question is what happens between reasoning steps. Return to the red mug. Suppose an intermediate image suggests that the gripper is near it, and the next step predicts a robot state. That transition has to determine what should happen next while also translating visual evidence into a different representational vocabulary. The relation that matters—whether the fingers are positioned to secure this particular mug—must survive that translation.
This is the fragmentation we care about. A system can retain the object, the fingers, and their individual features while failing to maintain the relation needed for the next decision. Plausible outputs in each modality are an insufficient objective: a plausible image and a plausible gripper state can describe an implausible combination.
There is a second, subtler issue with the sequence. An image, a geometric description, and a robot state may refer to the same instant. Ordering them as image → 3D → state is a choice about computation; it does not make one observation the physical cause of the next. Such a factorization is mathematically valid. What we wanted to relax was the requirement that advancing a thought also means choosing and producing its next modality-specific expression.
The Platonic Representation Hypothesis [2] offers a useful connection. Huh and colleagues study representational alignment across models and modalities, and hypothesize convergence toward a shared statistical description of reality. They also emphasize that different sensors carry different information. We take this as motivation for a design question: can different observations train an internal representation that later computation can use in a common way? It is not a guarantee that all modalities should become identical.
In fact, forcing identical information would defeat the purpose. Geometry may reveal clearance that a caption omits; robot state may reveal something invisible to the camera. A useful shared workspace must accommodate these differences while making their consequences accessible to the same reasoner.
What should a thought preserve?
“One world” is a starting intuition, but reconstructing the entire world is an unnecessarily demanding training objective. For Figure 1’s visual question, identifying the red mug beside the blue book may be sufficient. For its grasping task, the workspace must also retain information about the mug’s pose and the gripper’s relation to it. The book’s surface texture need not be reproduced to solve either task. The representation we want is shaped by what the task will need next.
Uni-LaDiR puts this into practice with a common latent interface. During training, modality-specific encoders turn teacher steps into features. A shared backbone compresses each step into the same-sized block of latent tokens, using learnable queries that can read only that step. The blocks share an output projection and a downstream consumer.
A block is therefore a local piece of teaching information, not a complete world state. The task input and accumulated latent prefix provide the context for subsequent reasoning. “Workspace” refers to this common computational interface; it does not imply that we have recovered an explicit simulator of reality.
Giving vectors the same shape is only the beginning. A block could preserve the mug’s color and still omit the geometry needed to grasp it. The learning objective must distinguish those choices. We train the latent prefix to help predict later teacher steps and the final answer or action, while hiding the earlier raw teacher steps from those predictions. This asks the constructor to preserve information that another computation will need. Reconstructing the source would instead reward preserving whatever makes that source easy to reproduce.
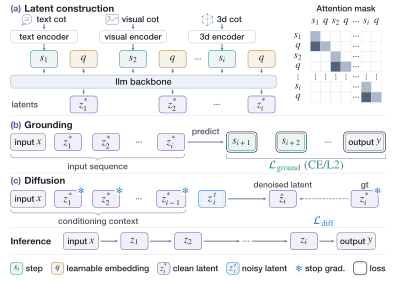
One backbone, three training views. Construction defines the interface; grounding makes its contents useful; diffusion learns to generate them. The bottom row shows what runs at inference.
The distinction changes how I think about intermediate supervision. An image or a state trace can teach the model something useful without becoming something the model must render on its way to an answer. Teachers provide evidence about how a task can be solved; they also help shape the interface in which the model learns to reason.
That leaves another requirement. A latent supplied by a teacher might be wonderfully informative and impossible to predict from the available input. At inference, the model has to produce its own states. Usefulness and generatability have to be learned together.
Why diffusion fits the shared workspace
A shared interface tells us where to reason. It leaves open how to produce the next state. The simplest option is a deterministic predictor: read the input and latent prefix, then predict the next block in one pass. That is an attractive baseline, especially when control latency matters.
The difficulty is that useful continuations need not be unique. In Figure 1’s mug scene, partial visibility can leave contact uncertain. Even with complete observations, both a handle grasp and a body grasp might be feasible. Each requires a compatible approach and finger configuration. These are hypothetical continuations of the same example, not alternatives decoded from the model.
Under squared-error regression, the optimal prediction is a conditional mean. If valid continuations occupy distinct regions, their mean need not itself be useful. Averaging two grasp configurations illustrates the concern, although the geometry of a learned latent space must be tested rather than assumed. This motivates a distribution over continuations; it does not, by itself, uniquely motivate diffusion.
The more specific reason to choose diffusion is the unit it updates: an entire latent block. A constructed block contains several continuous tokens that jointly encode one teacher step. Their coordinates have no prescribed interpretation as a sentence followed by an image followed by a robot state. Denoising lets the model update the block’s tokens together, conditioned on the task input x and earlier blocks z<i. It can form a candidate state without imposing an additional left-to-right generation order inside that block.
For the mug, the motivating requirement is that information relevant to object geometry and the gripper’s approach remain compatible as a candidate thought takes shape. Joint updates offer a way to coordinate those dependencies. We do not assign “handle” or “contact” to particular latent tokens, and joint updating alone does not guarantee a physically consistent grasp. Grounding supplies the pressure for the resulting representation to support the task.
This creates a useful division of work. The shared interface determines what can be carried between thoughts; diffusion provides an iterative way to construct the next thought in that interface. Across teacher modalities, the denoiser sees the same block format and learns the same kind of conditional transition. The modality-specific encoders still handle incoming teacher evidence during training.
Diffusion also exposes a computation choice: how many denoising evaluations to spend constructing each block. This can be varied separately from the number of reasoning blocks. More evaluations cost latency and do not automatically improve task performance. Our current results do not establish an optimal denoising budget or prove that extra steps recover earlier mistakes. Completed blocks remain fixed; the model generates the next block in sequence.
An autoregressive generator could also represent multiple continuations. A deterministic iterative model could also update a block jointly. The case for diffusion is their combination in a conditional generative process: sample from noise, coordinate the current block through repeated updates, then use the completed block as context. Whether that combination earns its cost is an empirical question, best answered with matched-compute and measured-latency comparisons.
During training, grounding and diffusion share a backbone. Grounding shapes what the constructor retains; flow matching [3] learns to generate its evolving targets. The targets are detached on the diffusion branch: joint training here does not backpropagate the answer loss through sampled denoising trajectories. At inference, generated blocks condition the answer or action without supplying or decoding teacher traces [1].
Results: better reasoning, with the source of the gains isolated
We evaluate the same design in two settings: visual reasoning with text and image teachers, and robot control with visual, 3D, and state teachers. The experiments answer two questions: does the complete method improve task performance, and does sharing help when the amount of supervision stays fixed?
1. Uni-LaDiR improves both visual reasoning and robot control
Setup. For visual reasoning, we use Qwen2.5-VL-7B [4] with Zebra-CoT [5] training traces and evaluate eight vision-centric benchmarks plus four mathematical or logical benchmarks. Robot control uses LIBERO [6] and RLBench [7] under the LaST₀ [8] protocol. These are separate model instantiations with a common design.

Results. Mean accuracy on the eight vision benchmarks improves from 63.55% to 75.55%, a 12.00-point gain over the matched base model ([1], Table 1). On visual math and logic, Uni-LaDiR reaches 49.03%, compared with 45.68% for the strongest reported four-benchmark comparator, ILVR [9]. The improvement is not universal: MathVista [10] is 73.2%, slightly below Vision-R1’s 73.5% [11].
On RLBench, mean success increases from 82% to 87% over LaST₀. Uni-LaDiR runs at 14.7 Hz, compared with LaST₀’s 15.4 Hz and explicit CoT-VLA’s 1.1 Hz [12], without action chunking ([1], Table 3). On LIBERO, it reaches 99.15% mean success across four suites.
Conclusion: the unified latent design improves visual answers and continuous control. On RLBench, it trades a modest reduction in control frequency relative to LaST₀ for higher success, while remaining much faster than explicit CoT-VLA.
2. Sharing helps beyond adding more teachers
The headline results establish capability, but additional teachers can help even when their representations remain separate. To test the interface itself, we fix the teachers, backbone, total latent budget, trainable parameters, training schedule, and inference compute, and vary which modalities share a latent space.

Results. Sharing text and image raises four-benchmark mean accuracy from 62.97% to 67.66%: +4.69 points, or +7.4% relative. For robot control, sharing visual, 3D, and state teachers raises the LIBERO/RLBench mean from 90.05% to 93.08%: +3.03 points, or +3.4% relative. All three together outperform every two-modality grouping; the best pair reaches 91.25% ([1], sharing ablations).
Conclusion: the benefit survives when supervision and budgets are held fixed. In these experiments, giving complementary teachers a common interface works better than keeping separate spaces, and full sharing works better than partial sharing.
I read this result as evidence that the important unit of supervision may be a relation spanning several observations. In the mug example, appearance identifies the target, geometry constrains the approach, and robot state describes the fingers. Their value to a grasp depends on how they fit together. Full sharing is consistent with making those dependencies easier for one consumer to use.
That interpretation is more specific than “more modalities help”: every configuration already receives the same teachers. But full sharing could also benefit optimization or parameter reuse. The experiment supports the design choice; it does not establish that the gain comes from learning the particular relations in our example. The next step is to change one relation while holding the others fixed, and test whether the model’s decision changes appropriately.
3. The shared space needs downstream grounding and joint training
A common vector width does not specify what information to retain, or whether the reasoner can generate it. We test those two requirements separately, keeping architecture and budgets fixed within each comparison ([1], objective and joint-training ablations).
| Design question | Comparison | Six-task mean score (%) | Relative gain |
|---|---|---|---|
| What should a latent preserve? | Source reconstruction → downstream grounding | 72.87 → 77.15 | +5.9% |
| How should we learn its generator? | Separate stages → joint training | 75.01 → 77.15 | +2.9% |
The mean combines accuracy on V* [13], MMVP [14], MathVista [10], and EMMA [15] with success on LIBERO and RLBench. It is an ablation summary, distinct from the main benchmark averages above. For a concrete task-level comparison, joint training raises RLBench success from 84.5% to 87.0% over separate stages.
Conclusion: unification works best when the task shapes the latent contents and construction is learned together with generation. Sharing a format alone leaves both requirements unresolved.
Conclusion
Uni-LaDiR makes two connected choices: a shared, task-relevant interface for intermediate reasoning, and diffusion to model how reasoning can continue within it. The first allows heterogeneous teachers to shape a common workspace. The second represents possible next states without requiring a thought to be rendered as text, an image, or a geometric reconstruction.
The experiments support three concrete findings: the complete design improves visual reasoning and control; sharing helps with fixed teachers and budgets; and downstream grounding plus joint training makes that shared space more effective. Together, they support treating multimodal reasoning as the evolution of a common computational context.
The next question is how reusable that context really is. In the red-mug scene, if an image and a geometric observation convey the same grasp-relevant relation, can one teacher’s latent replace the other’s without disrupting the next decision? If geometry reveals additional clearance information, does that information change the decision appropriately? That is a stronger test of the goal we started with: preserving the joint implications of different views of the same world.
Method and results: our September 14, 2026 manuscript, Sections 2–3 and supplementary sharing, objective, and joint-training tables. Figures 1–2 reuse the paper's vector originals; Figures 3–4 are replotted from manuscript measurements. Chart data.
References
- Uni-LaDiR: Latent Diffusion Unifies Multimodal Reasoning. Unpublished manuscript, September 14, 2026 version. Sections 2–3 and supplementary ablation tables. Source of this post’s method, figures, and experimental scores; a public manuscript link is not yet included. Chart data.
- Minyoung Huh, Brian Cheung, Tongzhou Wang, and Phillip Isola. The Platonic Representation Hypothesis. ICML, 2024.
- Yaron Lipman, Ricky T. Q. Chen, Heli Ben-Hamu, Maximilian Nickel, and Matt Le. Flow Matching for Generative Modeling. ICLR, 2023.
- Shuai Bai et al. Qwen2.5-VL Technical Report. arXiv:2502.13923, 2025.
- Ang Li et al. Zebra-CoT: A Dataset for Interleaved Vision Language Reasoning. arXiv:2507.16746, 2025.
- Bo Liu et al. LIBERO: Benchmarking Knowledge Transfer for Lifelong Robot Learning. NeurIPS, 2023.
- Stephen James, Zicong Ma, David Rovick Arrojo, and Andrew J. Davison. RLBench: The Robot Learning Benchmark & Learning Environment. IEEE Robotics and Automation Letters, 2020.
- Zhuoyang Liu et al. LaST₀: Latent Spatio-Temporal Chain-of-Thought for Robotic Vision-Language-Action Model. arXiv:2601.05248, 2026.
- Shuai Dong, Siyuan Wang, Xingyu Liu, Chenglin Li, Haowen Hou, and Zhongyu Wei. Interleaved Latent Visual Reasoning with Selective Perceptual Modeling. ACL, 2026.
- Pan Lu et al. MathVista: Evaluating Mathematical Reasoning of Foundation Models in Visual Contexts. ICLR, 2024.
- Wenxuan Huang et al. Vision-R1: Incentivizing Reasoning Capability in Multimodal Large Language Models. ICLR, 2026; first released in 2025.
- Qingqing Zhao et al. CoT-VLA: Visual Chain-of-Thought Reasoning for Vision-Language-Action Models. CVPR, 2025.
- Penghao Wu and Saining Xie. V*: Guided Visual Search as a Core Mechanism in Multimodal LLMs. CVPR, 2024.
- Shengbang Tong et al. Eyes Wide Shut? Exploring the Visual Shortcomings of Multimodal LLMs. CVPR, 2024. Introduces MMVP.
- Yunzhuo Hao et al. Can MLLMs Reason in Multimodality? EMMA: An Enhanced MultiModal ReAsoning Benchmark. arXiv:2501.05444, 2025.